Comparing text-to-speech engines for AI agents across eight checks
We measured ten streaming voice configurations from Northern Europe across eight checks, with HeyGen’s finished-file route reported separately for language coverage.

An AI agent needs speech to start promptly, but speed is only one part of the choice. A provider can return audio quickly while refusing a language, and a benchmark can look quicker when it repeats a sentence a service has already seen.
We compared 11 text-to-speech engines across eight checks. Ten streaming configurations were timed from Northern Europe on 10 October 2026. HeyGen's finished-file stock-voice route is included separately for voice-over. On 14 October we reran recognizer checks on saved greetings and replaced Fish's earlier reference-voice number samples.
1. Start speed
We sent complete greeting sentences and timed the first audio byte, excluding TCP/TLS setup. Fifteen sequential tries per accepted language/configuration; the scorecard shows the range of language medians.
Cartesia's greeting range was 0.11–0.26 seconds. ElevenLabs v4 Turbo was 0.16–0.27 seconds. Those figures describe these configurations and this region; they are not a universal ranking or whole-call response times.
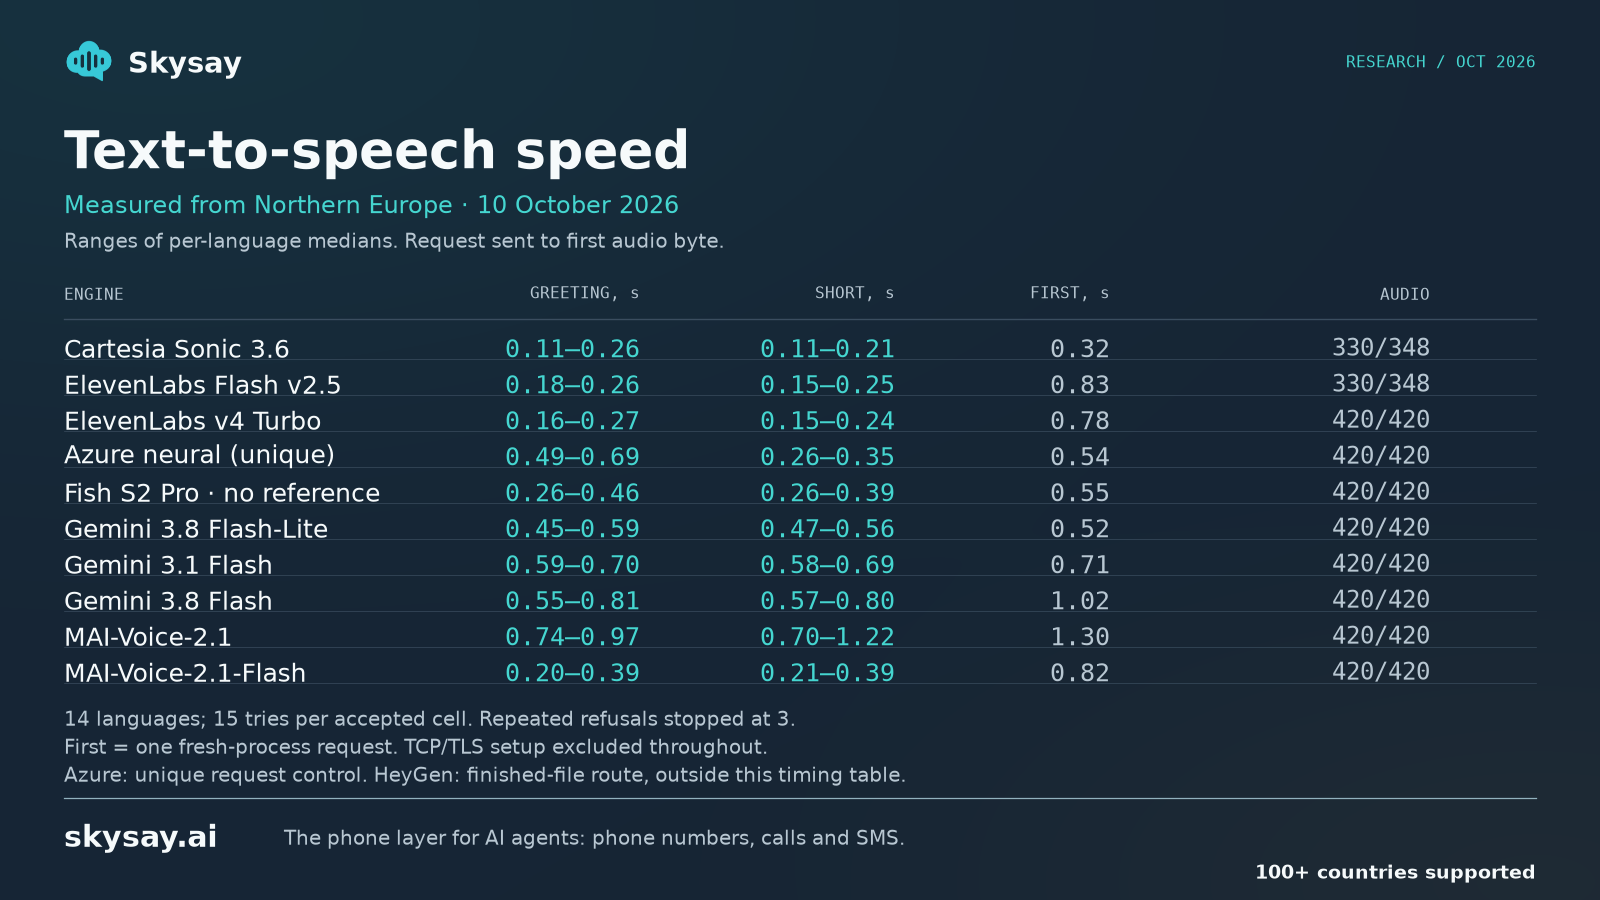
| Engine | Greeting, s | Short line, s | Usable / sent | Process-first, s |
|---|---|---|---|---|
| Cartesia Sonic 3.6 | 0.11–0.26 | 0.11–0.21 | 330/348 | 0.32 |
| ElevenLabs Flash v2.5 | 0.18–0.26 | 0.15–0.25 | 330/348 | 0.83 |
| ElevenLabs v4 Turbo | 0.16–0.27 | 0.15–0.24 | 420/420 | 0.78 |
| Azure neural (unique requests) | 0.49–0.69 | 0.26–0.35 | 420/420 | 0.54 |
| Fish Audio S2 Pro | 0.26–0.46 | 0.26–0.39 | 420/420 | 0.55 |
| Gemini 3.8 Flash-Lite TTS | 0.45–0.59 | 0.47–0.56 | 420/420 | 0.52 |
| Gemini 3.1 Flash TTS | 0.59–0.70 | 0.58–0.69 | 420/420 | 0.71 |
| Gemini 3.8 Flash TTS | 0.55–0.81 | 0.57–0.80 | 420/420 | 1.02 |
| MAI-Voice-2.1 | 0.74–0.97 | 0.70–1.22 | 420/420 | 1.30 |
| MAI-Voice-2.1-Flash | 0.20–0.39 | 0.21–0.39 | 420/420 | 0.82 |
2. Short replies
The closing line tests a smaller amount of speech. v4 Turbo's short-line medians were 0.15–0.24 seconds; Fish S2 Pro, with no reference voice, was 0.26–0.39 seconds. MAI-Voice-2.1 ranged from 0.70 to 1.22 seconds. A short sentence can still carry substantial request overhead, so greeting speed alone does not describe every turn.
3. Languages returning audio
The main set contains en, es, fr, de, it, pt, nl, fi, sv, uk, ta, et, lv and lt. Russian is excluded.
Cartesia and ElevenLabs Flash returned audio for 11/14 languages and refused Estonian, Latvian and Lithuanian with HTTP 400. The other eight streaming configurations returned audio for all 14. Returning a file does not establish that it contains the requested language.
HeyGen's stock-voice route also returned audio for 11/14 main languages and refused the same three Baltic languages. Its claimed list has 39 language codes; 38 were tested because Russian was excluded. HeyGen is outside the first-audio-byte speed table. We tested a finished-file route for voice-over, did not clone a voice and did not measure streaming. HeyGen speech API, claimed language list.
4. What the recognizers detected
Whisper-1 and Deepgram, requested as Nova-3, received one saved greeting per accepted configuration/language without a language hint. The 134 samples were checked at a 16 kHz baseline and after 8 kHz resampling. A match means the detector returned the requested language code; it is an automated proxy, not a voice-quality or pronunciation judgment.
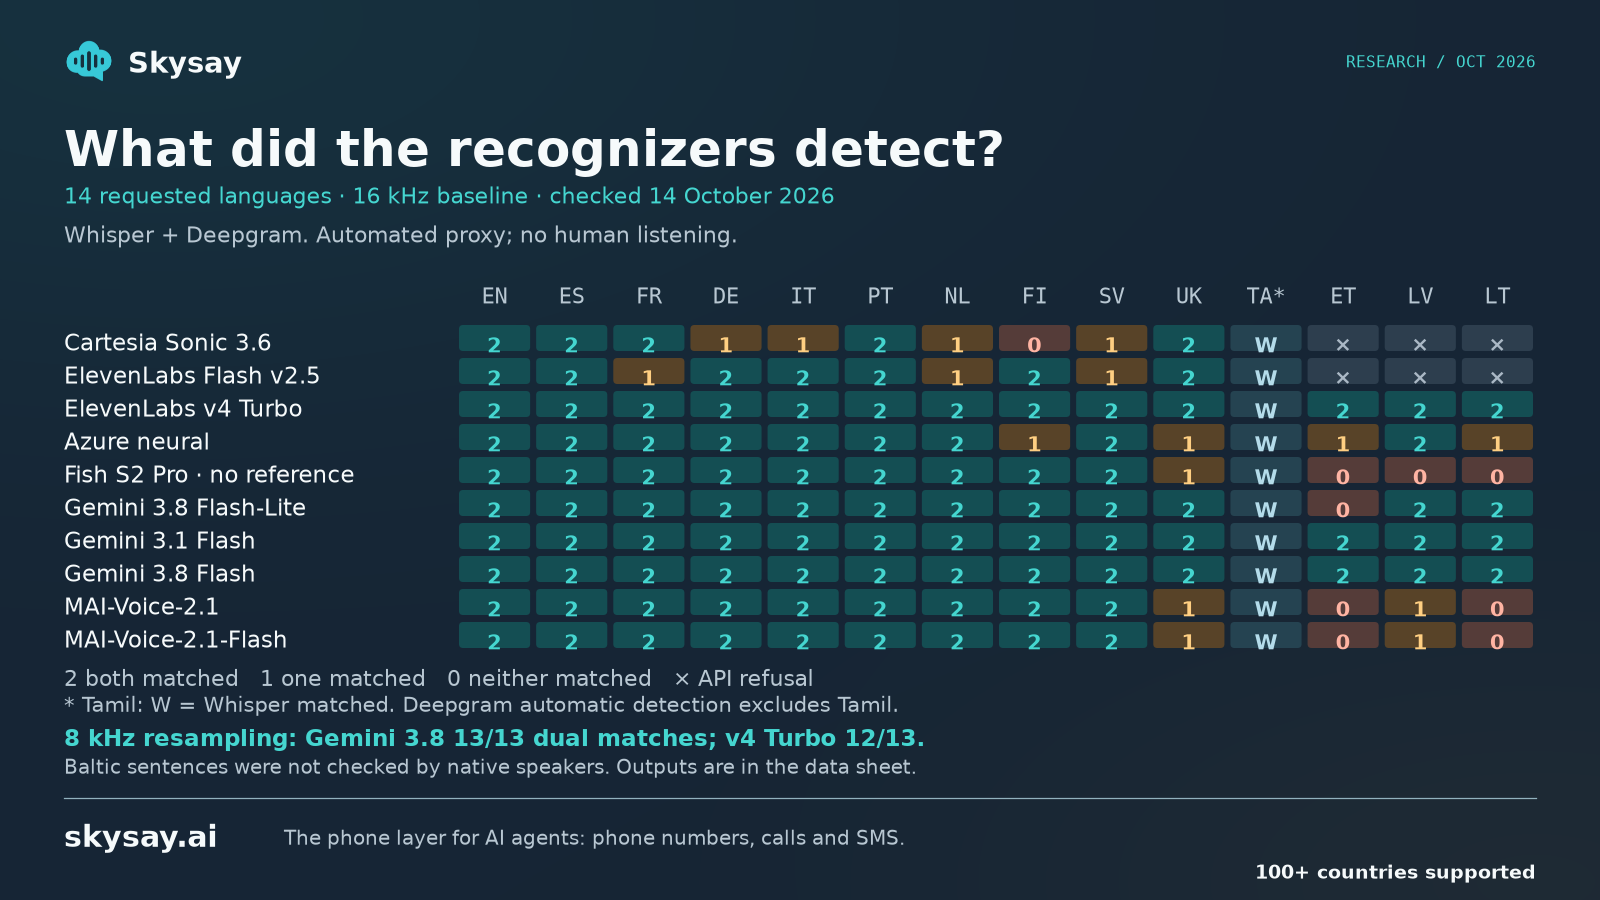
| Engine | Greeting audio returned | Both detectors matched at 16 kHz | Both matched after 8 kHz resampling |
|---|---|---|---|
| Cartesia Sonic 3.6 | 11/14 | 5/10 | 5/10 |
| ElevenLabs Flash v2.5 | 11/14 | 7/10 | 7/10 |
| ElevenLabs v4 Turbo | 14/14 | 13/13 | 12/13 |
| Azure neural | 14/14 | 9/13 | 10/13 |
| Fish Audio S2 Pro | 14/14 | 9/13 | 10/13 |
| Gemini 3.8 Flash-Lite TTS | 14/14 | 12/13 | 12/13 |
| Gemini 3.1 Flash TTS | 14/14 | 13/13 | 12/13 |
| Gemini 3.8 Flash TTS | 14/14 | 13/13 | 13/13 |
| MAI-Voice-2.1 | 14/14 | 9/13 | 9/13 |
| MAI-Voice-2.1-Flash | 14/14 | 9/13 | 9/13 |
At 16 kHz, v4 Turbo, Gemini 3.1 and Gemini 3.8 each had 13/13 dual-detector matches. After 8 kHz resampling, Gemini 3.8 retained 13/13; v4 Turbo and Gemini 3.1 had 12/13. For v4 Turbo's Estonian sample, Whisper returned et and Deepgram returned ko. For Gemini 3.1's Estonian sample, they returned et and fi.
Tamil is outside Deepgram's documented automatic detection set and is counted with Whisper only. Deepgram does support Tamil transcription when given a language hint. Nobody listened to these clips, and the sentences were not checked by native speakers. For Estonian, Latvian and Lithuanian, we publish refusals and recognizer outputs only. Deepgram language detection.
The 8 kHz pass is offline resampling. There were no carrier calls, codecs, packet loss or telephone noise in this experiment, so it does not establish how these voices will perform on a real phone connection.
5. Usable audio
The speed run, including the additional Azure control, sent 4,476 requests. Of these, 4,440 returned usable audio. All 36 failures were the Baltic-language HTTP 400 refusals from Cartesia and ElevenLabs Flash. No accepted-language speed request failed in this sample. That observation has a finite scope; it is not an uptime promise.
6. First request
The first request from a fresh process is reported separately: 0.32 seconds for Cartesia, 0.78 for v4 Turbo, 0.52 for Gemini Flash-Lite and 1.30 for MAI-Voice-2.1. The clock still excludes connection setup. One process-first observation cannot describe every server-side cold start, but it helps avoid presenting steady medians as the experience of every first call.
Azure also needs a repeated-text control. Greeting medians were 0.07–0.31 seconds on identical requests, compared with 0.49–0.69 seconds when each request had a unique SSML comment and the spoken text stayed the same. The main table uses the unique-request result. The difference is consistent with a cache effect; we did not inspect its internals.
7. Names, dates and times in the transcripts
The test sentence contains Martin Kask, 14 March and 9:30, with translations and three samples per language. Both recognizers received a language hint. An expected field matches if it appears in at least one transcript. A missing or ambiguous field remains unresolved; an agreed alternative requires both transcripts to clearly show the same different value.
The numerical comparison excludes the Baltic languages. This leaves 33 samples per engine. Fish's row uses its new no-reference samples; the others come from the 10 October report. No human pronunciation assessment was made.
| Engine | All four expected values found | Agreed alternative value | Unresolved |
|---|---|---|---|
| Cartesia Sonic 3.6 | 31/33 | 0 | 2 |
| ElevenLabs Flash v2.5 | 24/33 | 0 | 9 |
| ElevenLabs v4 Turbo | 33/33 | 0 | 0 |
| Azure neural | 27/33 | 0 | 6 |
| Fish Audio S2 Pro | 25/33 | 0 | 8 |
| Gemini 3.8 Flash-Lite TTS | 30/33 | 1 | 2 |
| Gemini 3.1 Flash TTS | 33/33 | 0 | 0 |
| Gemini 3.8 Flash TTS | 31/33 | 0 | 2 |
| MAI-Voice-2.1 | 29/33 | 0 | 4 |
| MAI-Voice-2.1-Flash | 30/33 | 0 | 3 |
For v4 Turbo and Gemini 3.1, all four expected values appeared in the transcripts on 33/33 non-Baltic samples. Fish had 25/33 and eight unresolved. An unresolved transcript is not proof that the engine said the wrong value.
8. Price
The billing units need to remain visible. ElevenLabs Flash and v4 Turbo are $40 per million characters. Azure neural and MAI Flash are $15 per million characters; MAI-Voice-2.1 is $22. Fish S2 Pro is $15 per million UTF-8 bytes, so its cost per character changes with the text's encoding. ElevenLabs, Azure, Microsoft MAI, Fish.
Cartesia's bundled plan equivalents are about $37–50 per million characters, with separate overage rates. Gemini charges text and audio tokens; the generated duration changes the character-equivalent estimate. The 3.8 Flash and Flash-Lite introductory rates are scheduled to change on 1 January 2027. We do not apply that change to 3.1. Prices were checked on 14 October, and the expired ElevenLabs promotion is excluded. Cartesia, Google.
The pricing sheet preserves the exact rates, sources and sample-specific token conversions. We did not find a verified public USD price for HeyGen's exact stock-voice route, so it has no character-equivalent price in this comparison.
Choosing a configuration
v4 Turbo combined low greeting and short-line medians, audio in all 14 languages, 420/420 usable speed responses and 33/33 transcript matches for the non-Baltic name/date/time samples. Its first request was slower than its steady medians, and one sample lost dual-detector agreement after 8 kHz resampling. Gemini 3.1 shared the 33/33 transcript result, while Gemini 3.8 retained dual-detector agreement on all 13 eligible 8 kHz greetings. There is enough detail here to choose what to test for a particular workload, without declaring an overall winner.
We build Skysay, the phone layer for AI agents. Build an agent in the workspace or connect one you already use, then give it phone numbers, calls and SMS. This study compares provider APIs; it does not claim that every tested engine is currently integrated into Skysay.
100+ countries covered. Pay as you go. Start with Skysay.


